Two recordings from the staging environment of the multi-tenant AI platform where I am the only AI engineer. Nothing here is a mockup.
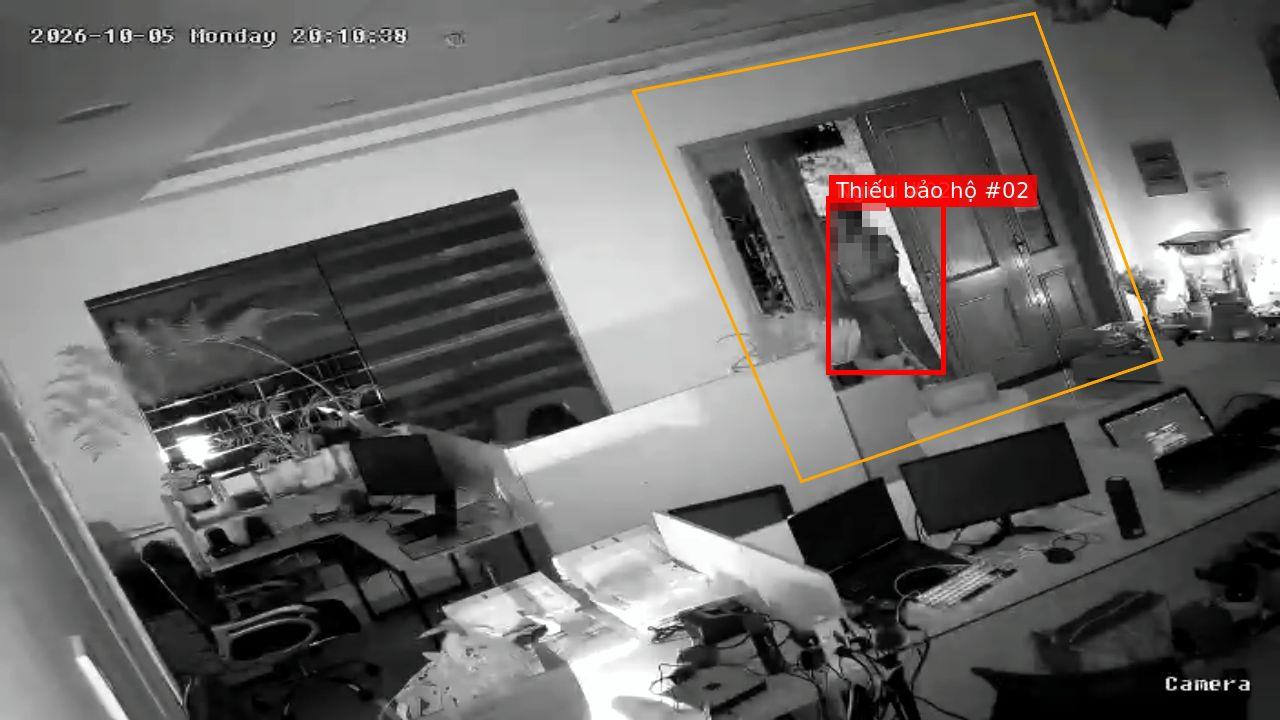
RECAI Box 3 · Camera 12300.0 s
HIGH New AI event
Intrusion · restricted zone
aibox-box3 · Camera 123 · yolo11m.engine
conf 0.81 · frame → event 71 ms
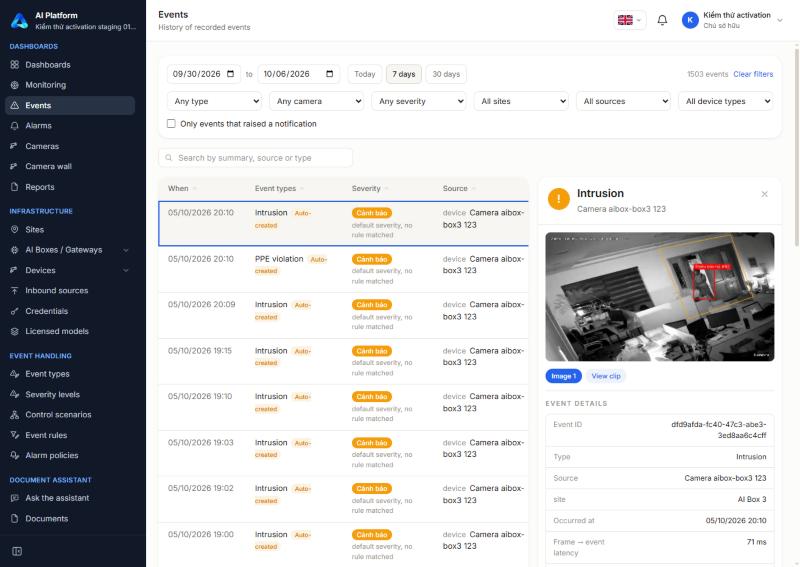
Fig. 1. An intrusion alert on AI Box 3, recorded 5 Oct 2026. The box and scores are the ones stored with the event, and the alert appears at the moment the event was raised. Faces are pixelated.
A person walks into a restricted zone
The AI box at the site reads the camera's RTSP stream and runs a YOLO11 TensorRT engine. When someone crosses the zone drawn for this camera, the box raises an event and the web portal receives it with a snapshot and the detection box.
Frame to event
71 ms
Frame to server
39 ms
Rules fired
intrusion 0.81, no PPE 0.89
Event feed
Waiting for the first event…
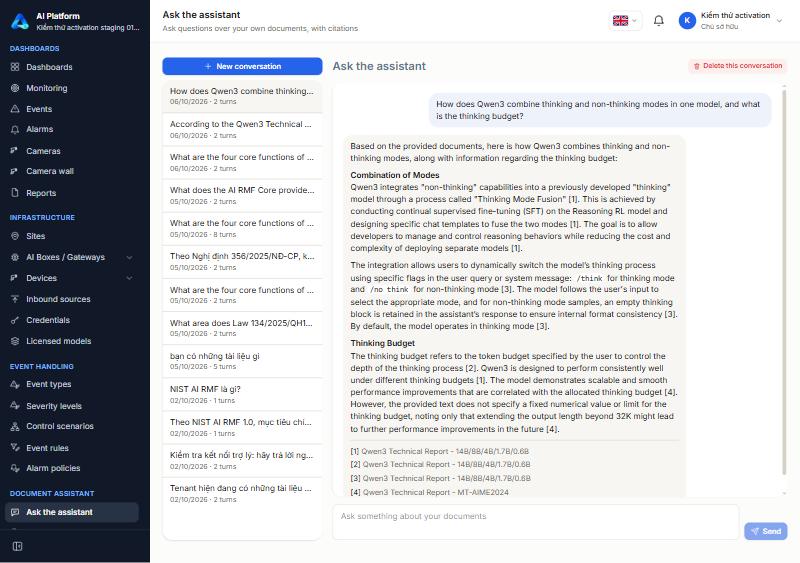
Document assistant0.0 s
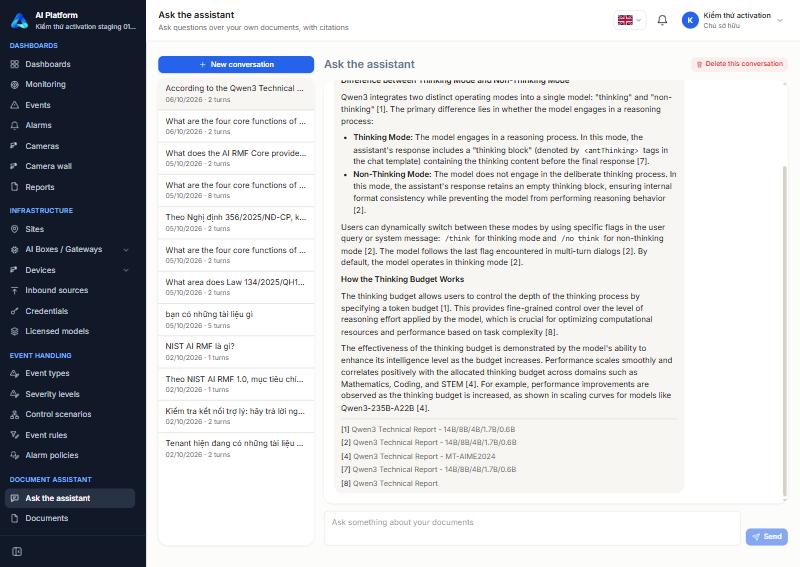
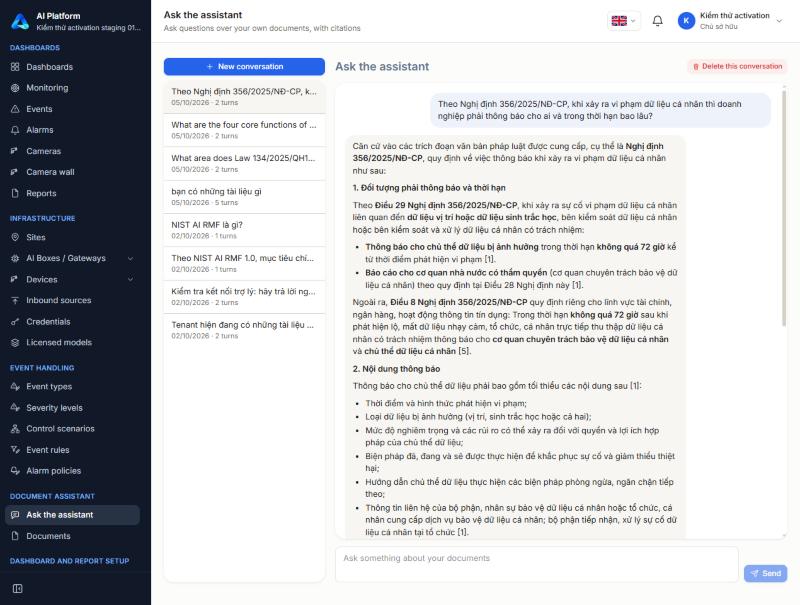
Fig. 2. A replay of a real answer from 6 Oct 2026, with the exact text and the timing measured in the browser.
A question answered from a technical report
I uploaded the Qwen3 Technical Report as a PDF and asked how the model mixes thinking and non-thinking modes. The answer took 9.5 seconds and cites the sections it used.
Analyse the question.
Hybrid search: bge-m3 dense vectors and BM25, fused with RRF in Qdrant.
Rerank the passages with a cross-encoder.
Answer with self-hosted Qwen on vLLM, streamed with citations.
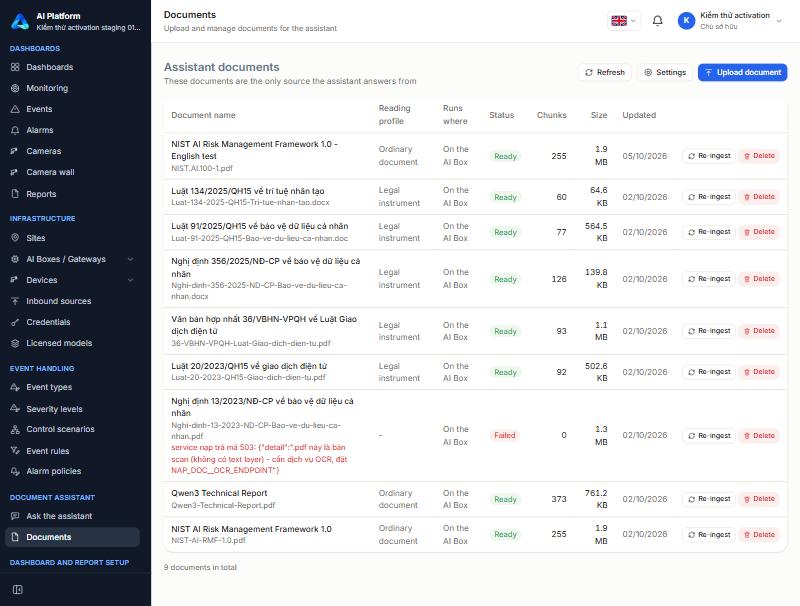
The same answer in the portal.Document library with indexing status.
Systems I have built
From retrieval and fine-tuning to edge deployment and speech. What each one does, and what it runs on.
Document Assistant
RAG · LLM · SaaS
A chat assistant inside a multi-tenant SaaS platform. Teams upload their own files and ask questions in English or Vietnamese, and every answer cites the section it came from.
Upload PDF, Word, Markdown or TXT. Indexing runs in the background.
Structure-aware chunking keeps headings and sections together.
Hybrid search with bge-m3 dense vectors and BM25 in Qdrant.
Streaming answers with numbered citations linked to the passage.
Each tenant sees only its own documents.
Self-hosted Qwen on vLLM, so no document goes to a third-party API.
Runs on a central GPU server or on a box at the customer's site.
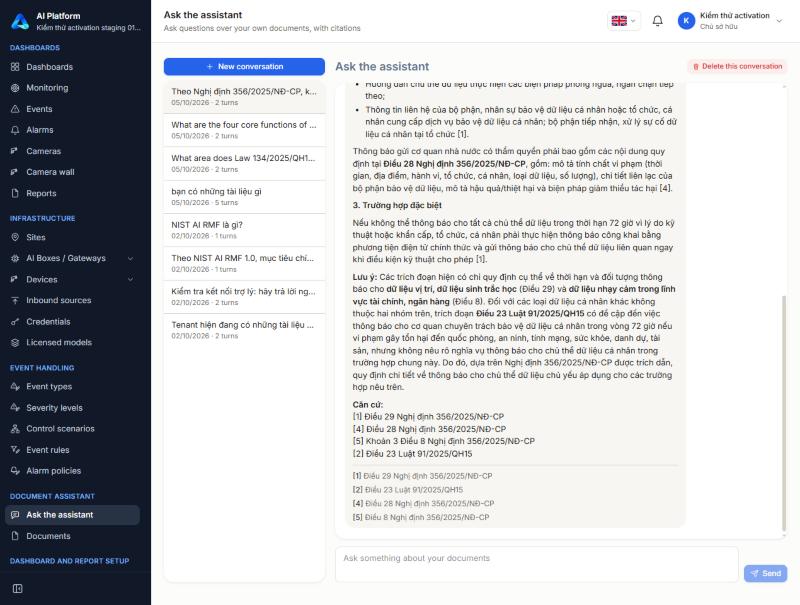
Fig. 4. The 72-hour breach notice in Decree 356/2025.Fig. 5. Citations by article and clause.
Edge AI Video Analytics
Computer vision · Edge AI · TensorRT
Cameras at each site stream to an AI box on the premises. Detectors run there, and events reach a central portal with a snapshot about 71 ms after the frame.
Multi-tenant portal: sites, AI boxes, cameras and users per customer.
Intrusion detection with restricted zones drawn per camera.
PPE detection for workers missing protective gear.
Every event stored with snapshot, clip, boxes, severity and latency.
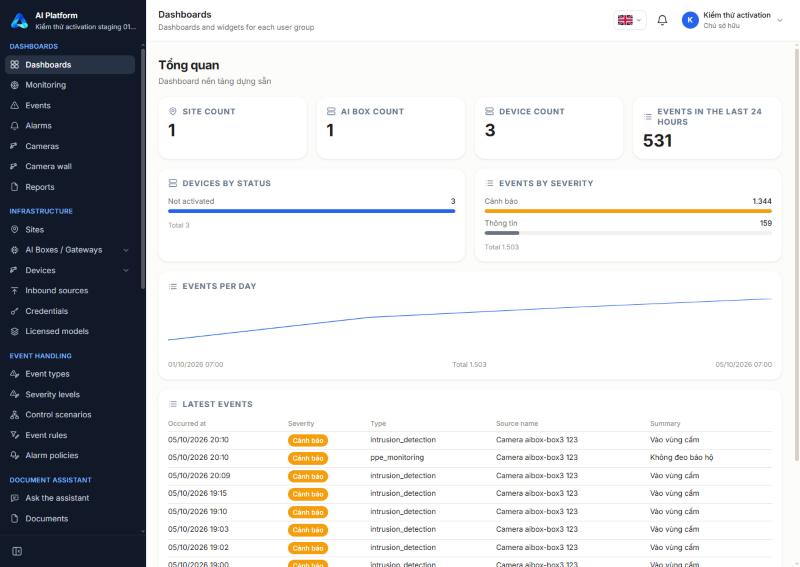
Dashboard with events per day and filters by site, camera and severity.
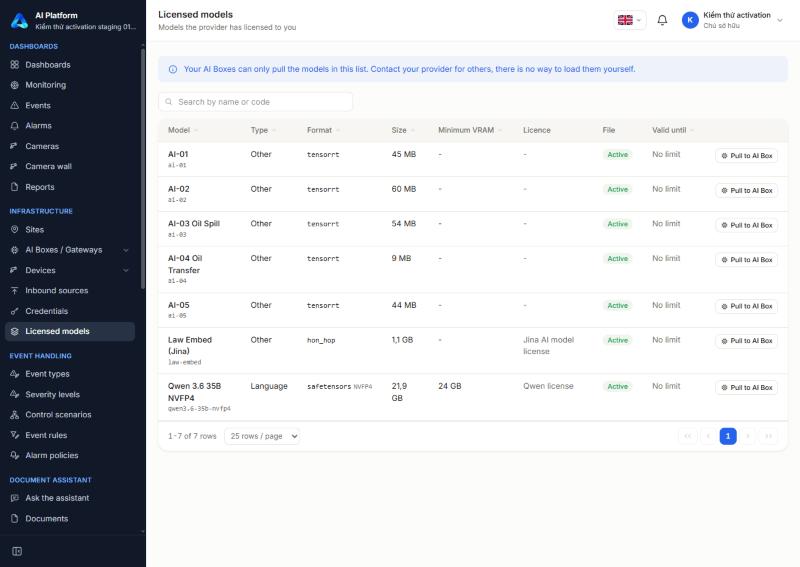
Licensed models packaged as TensorRT engines and pulled to the boxes.
Fine-tuned Qwen2.5-VL-7B with LoRA to answer multiple-choice questions about traffic-sign images.
0%1,437 of 1,500 test questions
Voice AI · Function calling · IoT
A voice assistant on an ESP32-S3
A small device you talk to. It sends speech to a server, an LLM decides what to do, and the device answers out loud. Function calling covers weather, news and music.
Vision models I have trained
Measured on independent QC test sets, not on the training split.
Task
Result
Notes
No-helmet detection
98.5% / 95.7%
Precision and recall, running in real time inside a C++ application.
Drowsiness detection
70% → 96%
Classroom video. Most of the gain came from fixing data balance and class definitions, not a bigger model.
Violence detection
93.2%
Class precision with MoViNet and frame voting on classroom video.
Talking detection
91%
Eye tracking combined with object detection.
Face anti-spoofing
80% → 87.5%
Improved by generating augmented spoof examples.
Text-to-person search
~1M people
Fine-tuned SigLIP2 to find people from descriptions like “man in a red jacket carrying a backpack”.
Table 2. Vision models and how they were measured.
The only AI engineer in a four-person product team: document assistant, edge video analytics platform, people and vehicle access management.
Mar 2025 – Mar 2026
Computer Vision Engineer, AIBOX
Vision and multimodal R&D: classroom video analytics on DeepStream (drowsiness, talking and violence detection) and SigLIP2 fine-tuning for text-based person retrieval.
2021 – 2026
Hanoi University of Science and Technology
Bachelor's degree in Control Engineering and Automation.
Have documents, images, video or audio you want AI to work on?
I take projects through Upwork, from a first prototype to a system running on your own servers.